Introducing Open Pseudonym: keep personal data away from AI models
An open specification and SDK that swaps names, contact details, dates and secrets for realistic stand-ins before text reaches a model, and puts the real values back on your side.
Open Pseudonym is an open specification and SDK from the Atlas Research Lab. It keeps personal data away from AI models without making them worse at the task. Version 0.2.0 is on PyPI and npm, free for anyone.
What problem does it solve?
To help with an email, a model has to read the email. Names, addresses, phone numbers, dates and sometimes a one-time code travel with it. Swapping them for labels like [NAME_1] protects the data but makes the model worse: it loses track of who said what, and date maths stops working.
How does it work?
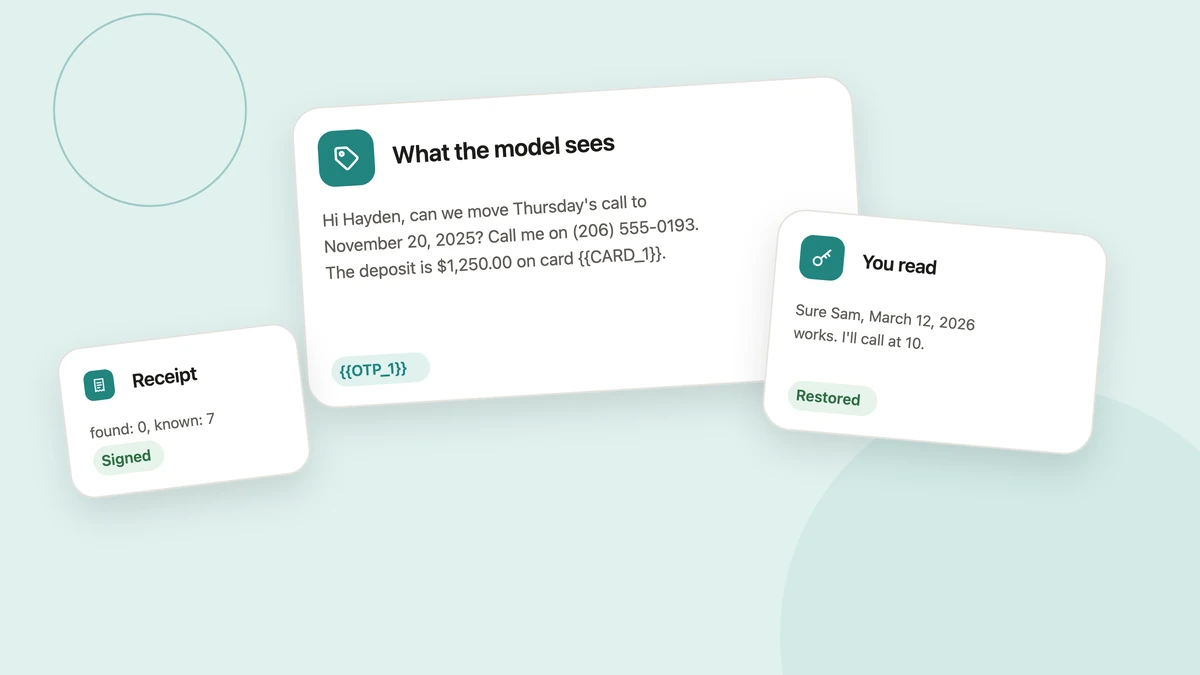
Before text reaches a model, Open Pseudonym swaps names, emails, phone numbers, dates and secrets for stand-ins chosen for the task at hand. The model works on the stand-ins. When it answers, the real values go back in on your side. The key that links the two never leaves your device, or your own server.
- It hides by task. A policy says what happens to each type of data for each kind of task. Scheduling keeps real dates so calendar maths works; a reply fakes the contact details. Code picks the policy and can only make it stricter. The model never picks.
- It keeps the model's context. The same person gets the same fake name everywhere, and dates move together by whole weeks, so Thursday stays Thursday.
- It proves what left. Before a request goes, its exact bytes are checked for every real value the vault knows. With receipts on, every request that goes gets a signed, hash-chained receipt you can check later.
What are secret handles?
Some values the model only needs to move, not read: a one-time code, a password, a card number. Open Pseudonym turns one into a handle such as {{OTP_1}} plus a short note, for example a 6-digit code from example.com. When an agent types the handle into a login box, a small local filler checks that the box is really on example.com, puts the real code in at the last moment and burns the handle. A prompt injection that asks for the code somewhere else gets a refusal.
What changed in 0.2?
A critic pass ran real sentences through the strictest level and found values that still reached the model. Version 0.2.0 closes those gaps:
- Names without a cue. A list of about 1,150 given names from many cultures catches “I met Priya” and “Daniel Smith signed”, and a name is never half hidden any more.
- More kinds of personal data. Record numbers (orders, patients, passports), usernames, places, postcodes, hospitals and banks.
- Dates that still make sense. Dates move by one to eight whole weeks, a holiday keeps its day, and a birth date keeps the person's age.
- Measured. Names found on the hand-written test set went from 86% to 100%, planted values that reached the model went from 1 of 25 to 0 of 28, and both SDKs pass 109 shared test vectors.
What does it not do?
It is pseudonymisation, not anonymisation. What reaches the model is still personal data in law, and a careful reader can sometimes work out who a text is about from what is left. A name that is not on the list and has no cue, or a name written in lower case, can still be missed, so apps should pass the names they already know. Health details and other rare facts are not hidden. The README lists every known limit, and says which benchmark numbers are optimistic.
How do I try it?
Install it with pip install open-pseudonym or npm install open-pseudonym, then follow the quick start on the Open Pseudonym page. The specification, test vectors and both SDKs are on GitHub. A hand-written test set from someone other than the author is the most useful contribution anyone could make right now.
Questions
Is Open Pseudonym anonymisation?
No. It is pseudonymisation: personal data is replaced so it cannot be tied to a person without extra information that is kept separately. What reaches the model is still personal data in law.
Which languages does it support?
Python and TypeScript. Both SDKs pass the same shared test vectors, so the same seed and clock give the same stand-ins in both.
Does it need a server?
No. The core runs inside your app. An optional local proxy speaks the OpenAI and Anthropic APIs; it has no login and is meant for one person on their own machine.
Is it free?
Yes. The code is Apache-2.0 and the specification text is CC BY 4.0.